



- FMEA scores control failures by Severity, Occurrence, and Detection, producing an RPN that replaces gut-feel prioritization with a defensible, documented rationale.
- A high-severity, frequently occurring, hard-to-detect control gap scores highest and gets remediation first, even if it has never caused a visible incident.
- FMEA is most valuable at three moments: ISO 27001 and SOC 2 risk assessments, change management when new systems introduce unknown risk, and post-incident reviews.
- The FMEA output is a prioritized risk register that directly satisfies ISO 27001 Clause 6.1, SOC 2 CC3, NIST SP 800-30, and PCI DSS Requirement 12.3.
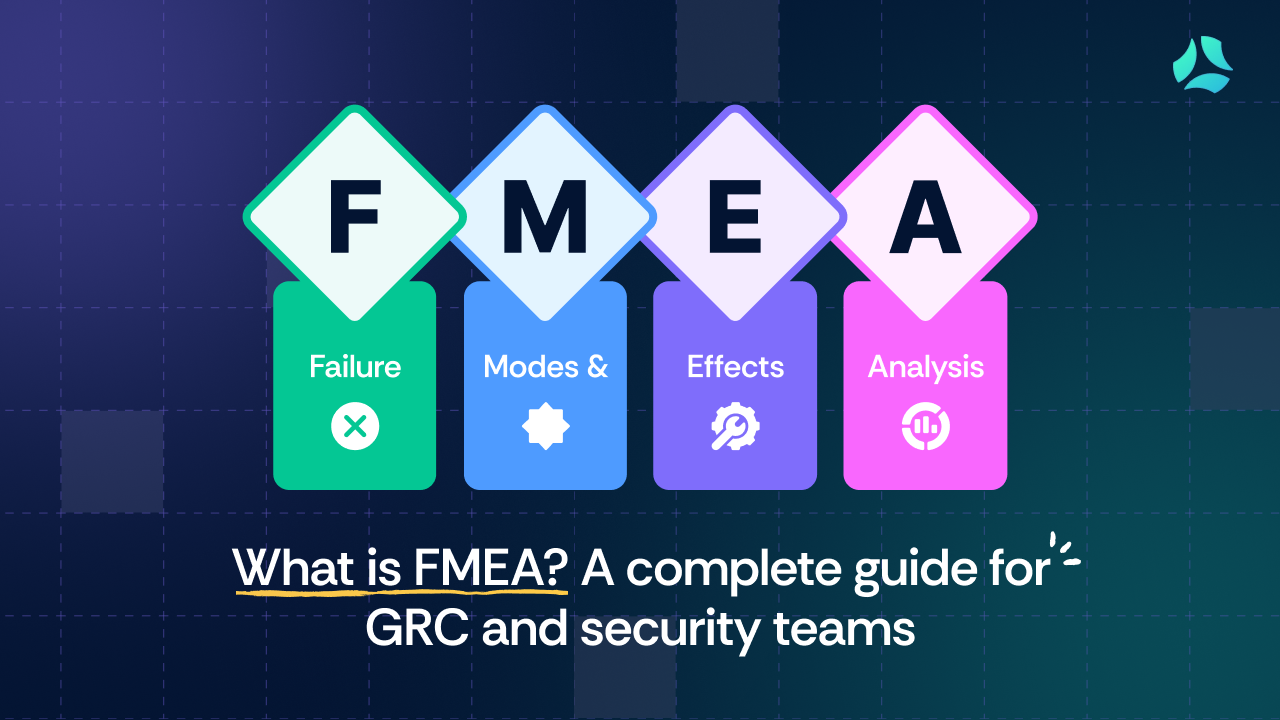
Failure Mode and Effects Analysis (FMEA) was developed in the 1940s for aerospace engineering and refined by the automotive industry into a standard risk assessment methodology. The general application of this term applies to brake systems, circuit boards, and production lines.
However, GRC and security teams deal with a different class of failure modes: access controls that exist on paper but not in practice, vendors who handle sensitive data without executed agreements, logging systems that collect data no one reviews, and risk assessments that get completed once and never updated.
These are not brake caliper failures. But they carry the same analytical structure: a failure mode, an effect, a cause, a severity, a likelihood, and a detection gap. FMEA handles them with exactly the precision those teams need.
This guide translates FMEA for the GRC and security context: how RPN scoring maps to control failures and vendor risk, how to run an FMEA in a compliance program, and how the output connects to ISO 27001, SOC 2, and NIST risk registers.
What FMEA is, translated for GRC teams
FMEA is a systematic method for identifying how a system or process can fail, what the consequences of each failure mode are, and how likely each failure is to occur and go undetected.
The output is a ranked list of failure modes ordered by their Risk Priority Number, which tells the team where to focus remediation effort.
In manufacturing, the system is a product or production process. In a GRC context, the system is the organization's control environment: the policies, technical controls, processes, and vendor relationships that are supposed to prevent security incidents, data breaches, and compliance failures.
The analytical steps are identical whether you are assessing a physical system or a compliance program.
- Identify what can fail.
- Determine what happens when it does.
- Score the severity, likelihood of occurrence, and likelihood of detection.
- Multiply to get the RPN.
- Prioritize remediation by RPN.
- Document the analysis.
That process is as useful for a GRC team preparing for a SOC 2 assessment as it is for an engineer certifying a medical device.
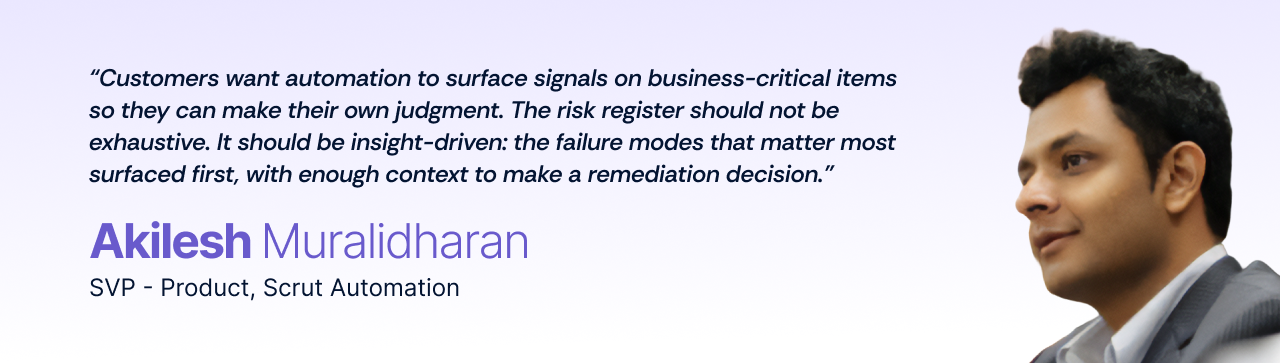
The FMEA methodology: How it works
Step 1: Define scope and assemble the team
FMEA works at the system level, so the first decision is what system you are analyzing.
For a GRC team, the scope might be a specific control domain (access management), a compliance framework boundary (the SOC 2 audit scope), a vendor relationship (a critical SaaS provider with access to customer data), or a change being introduced (a new cloud infrastructure deployment).
Assembling the right team matters because FMEA surfaces failure modes that no single person sees.
For a security FMEA, that typically means a GRC lead, a security engineer, a system or process owner, and in vendor risk scenarios, representation from legal or procurement. The analysis is only as complete as the knowledge in the room.
FMEA forces the right people into one room to agree on what the failure modes are before the auditor walks in.
Step 2: Identify potential failure modes
A failure mode is a specific way a control, process, or system can fail to perform its intended function. In a security FMEA, failure modes are not incidents. They are the conditions that make incidents possible.
Examples for a GRC team assessing access management controls:
- MFA enforcement policy exists but is not technically enforced on service accounts
- Access review process is documented but review completion is not tracked or evidenced
- Offboarding checklist includes access revocation but no automated verification that it occurred
- Privileged access is granted through a request process but approvals are not logged
Each of these is a failure mode: a gap between how the control is supposed to work and how it actually works.
Step 3: Identify failure effects and causes
For each failure mode, document two things. The effect is what happens to the system or business if this failure mode is present. The cause is the upstream condition that produces the failure mode.
Using the MFA enforcement failure mode above: the effect is that a compromised service account credential provides unauthorized access to systems in scope, with potential data exposure and a SOC 2 CC6.1 finding.
The cause is that MFA enforcement was configured for user accounts but the policy exemption for service accounts was never reviewed or removed.
Documenting causes is what makes FMEA a remediation tool. Fixing the effect without addressing the cause produces a temporary fix. Fixing the cause, in this case reviewing and removing the MFA exemption and implementing a formal exception process with approval and expiry, addresses the structural gap.
Step 4: Score severity, occurrence, and detection
Each failure mode receives three scores on a 1 to 10 scale:
- Severity (S): How serious is the impact if this failure mode is present? A score of 1 means negligible impact. A score of 10 means catastrophic impact, such as a material data breach, regulatory enforcement action, or loss of a major customer. In a GRC context, severity maps to business impact, regulatory exposure, and audit consequence.
- Occurrence (O): How likely is this failure mode to occur or already be present? A score of 1 means the failure is extremely unlikely given current controls. A score of 10 means the failure is virtually certain or already observed. Prior audit findings, penetration test results, and vulnerability scans are direct inputs to occurrence scoring.
- Detection (D): How likely is it that existing monitoring and review processes would catch this failure before it causes harm? A score of 1 means the failure is almost certain to be detected immediately. A score of 10 means no detection mechanism exists. Logging, automated monitoring, and review processes directly affect detection scores.
Step 5: Calculate the Risk Priority Number
RPN = Severity x Occurrence x Detection
The RPN ranges from 1 to 1,000. Higher scores indicate failure modes that are severe, likely, and hard to detect. These receive priority remediation resources. Lower scores indicate failure modes that are either less severe, less likely, or more reliably detected before they cause harm.
RPN is a priority ranking tool, not an absolute risk measure. Two failure modes with the same RPN can have very different risk profiles. A score of 200 produced by Severity 10 x Occurrence 2 x Detection 10 represents a catastrophic but rare and undetected failure, very different from Severity 4 x Occurrence 5 x Detection 10. When RPNs are close, review the individual component scores before setting remediation priority.
In a GRC context, high-severity failure modes warrant immediate attention regardless of their final RPN.
A severity score of 9 or 10 should trigger remediation review even if occurrence and detection bring the overall RPN below the threshold set for automatic escalation.
Step 6: Prioritize remediation and document
Sort failure modes by RPN from highest to lowest. Define a threshold above which failure modes receive immediate remediation resources, commonly RPN 200 or higher, though the right threshold depends on the organization's risk tolerance and the scale of the analysis.
See Scrut's audit risk model guide for how auditors apply similar weighting logic when prioritizing which controls to test.
For each high-priority failure mode, document the recommended remediation action, the control owner responsible for implementing it, the target completion date, and the expected post-remediation RPN assuming the action is completed. This post-remediation RPN gives leadership a clear picture of the risk reduction achieved by the remediation investment.
A worked example: Security FMEA for a vendor risk assessment
A SaaS company is onboarding a new data processing vendor that will receive customer records as part of a CRM integration. The GRC team runs an FMEA to identify and prioritize vendor risk before the integration goes live.
Three failure modes score above RPN 200 and receive immediate remediation: the missing vendor security assessment (392), the undefined data retention policy (336), and the absence of a BAA (270).
The sub-processor disclosure gap (280) is also above threshold. The breach notification timeline gap (192) falls below the threshold but is flagged for the next contract renewal.
This output gives the GRC team a defensible, evidence-based rationale for blocking the integration until the top three items are resolved, and a clear remediation plan with owners and timelines. It also produces audit-ready documentation for ISO 27001 Annex A 5.19 (supplier relationships), SOC 2 vendor management criteria, and HIPAA BAA requirements.
The same logic applies to vendor risk: a vendor with a SOC 2 report that does not reflect actual control operation is not a secured vendor. FMEA forces you to look at what the controls actually do, not just what the paperwork says.
When to run a security FMEA
FMEA is most valuable at three specific moments in a security and compliance program.
During risk assessments for ISO 27001 or SOC 2
ISO 27001 Clause 6.1 requires organizations to identify information security risks and assess their potential consequences and likelihood. SOC 2 requires a risk assessment process as part of the CC3 criteria.
FMEA provides a structured methodology for both, producing the documented analysis, scoring rationale, and remediation plan that auditors expect. An FMEA worksheet is direct evidence of a functioning risk assessment process.
During change management and product launches
New infrastructure deployments, product launches, third-party integrations, and organizational changes all introduce failure modes that the existing control environment was not designed to address. Running a scoped FMEA on changes before they go live surfaces control gaps while remediation is still inexpensive, before the change is in production and before the next audit cycle.
After an incident or near-miss
An incident is evidence that at least one failure mode was present. A post-incident FMEA uses the incident as a seed to identify related failure modes: similar controls in adjacent systems, the same root cause appearing in a different process, detection gaps that allowed the incident to persist. The output is a remediation plan that addresses the class of failure at its root, going beyond the specific instance that triggered the review.
“Annual compliance is like entropy: everything tends toward disorder. ”
— Beau Butaud, Co-founder, Render Compliance
Check controls quarterly to catch gaps. The failure modes FMEA surfaces between audits are almost always more costly to fix after an auditor finds them than they would have been to address during a routine review.
How FMEA output connects to compliance frameworks
FMEA limitations GRC teams should know
- RPN multiplication can mask high-severity risks. Two failure modes with the same RPN can have very different risk profiles. A severity 10 x occurrence 1 x detection 10 failure mode scores 100, the same as severity 5 x occurrence 4 x detection 5. Always review severity scores independently before relying solely on RPN ranking.
- Scoring is subjective without anchors. Occurrence and detection scores in particular can diverge between assessors by two or three points without defined anchor descriptions for each score level. Define what a 3, 5, 7, and 9 mean specifically for your environment before running the analysis.
- FMEA identifies known unknowns, not unknown unknowns. It surfaces failure modes that the assembled team can identify and articulate. Novel attack vectors, zero-day vulnerabilities, and black swan events are outside its scope. FMEA should complement, not replace, threat intelligence and external penetration testing.
- FMEA is a point-in-time analysis. The control environment changes continuously. An FMEA completed 18 months ago before a major cloud migration does not reflect current risk. Build periodic FMEA reviews, at minimum annually and at every major system change, into the program.
How Scrut supports FMEA-driven risk management
Running an FMEA produces a prioritized list of control failures and vendor risks. The value of that list depends on what happens next: whether remediation is tracked, whether evidence of control improvement is collected, and whether the risk register reflects current posture, continuously updated as the environment changes.
Scrut's risk management capabilities are built for the post-FMEA workflow. Identified failure modes translate directly into risk register entries with severity scores, likelihood ratings, treatment decisions, and named owners.
For GRC teams that run FMEA as part of their risk assessment cycle, Scrut provides the operational infrastructure that turns the analysis output into a live, auditable risk management program.
See how Scrut helps GRC and security teams manage risk systematically across ISO 27001, SOC 2, NIST, and PCI DSS. Request a demo.
FMEA stands for Failure Mode and Effects Analysis. It is a structured risk assessment methodology that identifies how a system, process, or control can fail (the failure mode), what the consequences of that failure are (the effects), and how likely the failure is to occur and go undetected. The output is a Risk Priority Number (RPN) for each identified failure mode, which allows teams to rank and prioritize remediation objectively.
A standard risk assessment typically identifies risks and rates their likelihood and impact at a high level. FMEA adds a third dimension: detection, the likelihood that existing controls or monitoring processes will catch the failure before it causes harm. This makes FMEA more granular and more useful for prioritizing remediation because it distinguishes between a severe risk that is well monitored and likely to be caught, and a severe risk with no detection mechanism that will go unnoticed until it causes damage. FMEA also structures the analysis around specific failure modes, producing more actionable output than broad risk category assessments. See Scrut's cyber risk management frameworks guide for how FMEA output connects to the major frameworks.
Threat modeling identifies adversarial threats: who might attack the system, what their capabilities are, and which attack vectors they might use. FMEA identifies failure modes: how controls and processes can fail to function as designed, regardless of whether the failure is caused by an attacker, a human error, a process gap, or a system misconfiguration. The two are complementary. Threat modeling informs which failure modes are most likely to be exploited. FMEA provides the scoring and prioritization methodology for deciding which failures to remediate first. Mature security programs use both.
Yes, and it is particularly effective for this purpose. Vendor risk FMEA treats the vendor relationship as the system being analyzed and identifies failure modes in the contractual, operational, and security controls governing that relationship. Common vendor risk failure modes include missing or outdated business associate agreements, undisclosed sub-processors, undefined breach notification timelines, and unverified security control coverage. RPN scoring allows GRC teams to rank vendor risks objectively and make data-driven decisions about onboarding gates, contract terms, and ongoing monitoring requirements. The worked example in this blog walks through exactly this scenario. See also vendor risk assessment challenges with AI for how automation is changing the vendor risk identification process.
At minimum, annually as part of the risk assessment cycle required by ISO 27001, SOC 2, and NIST frameworks. In practice, a scoped FMEA should also be triggered by material changes to the control environment: new cloud infrastructure deployments, significant product changes, new vendor relationships handling sensitive data, major workforce changes, and security incidents or near-misses. Organizations that treat FMEA as a periodic exercise tied only to audit cycles miss the failures introduced between cycles. The most effective programs integrate FMEA into change management as a lightweight trigger-based exercise alongside the annual compliance cycle.