



- Effective AI risk management strategies go beyond threat lists. They require ongoing risk assessment tied to the AI system's lifecycle, deployment model, and context.
- The NIST AI RMF (Govern, Map, Measure, Manage) and ISO 42001 are the two primary voluntary frameworks. Neither prescribes exact controls, so you must adapt both to your context.
- Prompt injection, unintentional training data exposure, model drift, and supply-chain poisoning are the four risks most likely to go unaddressed without a structured program.
- Define your AI risk tolerance before deployment, not after an incident.
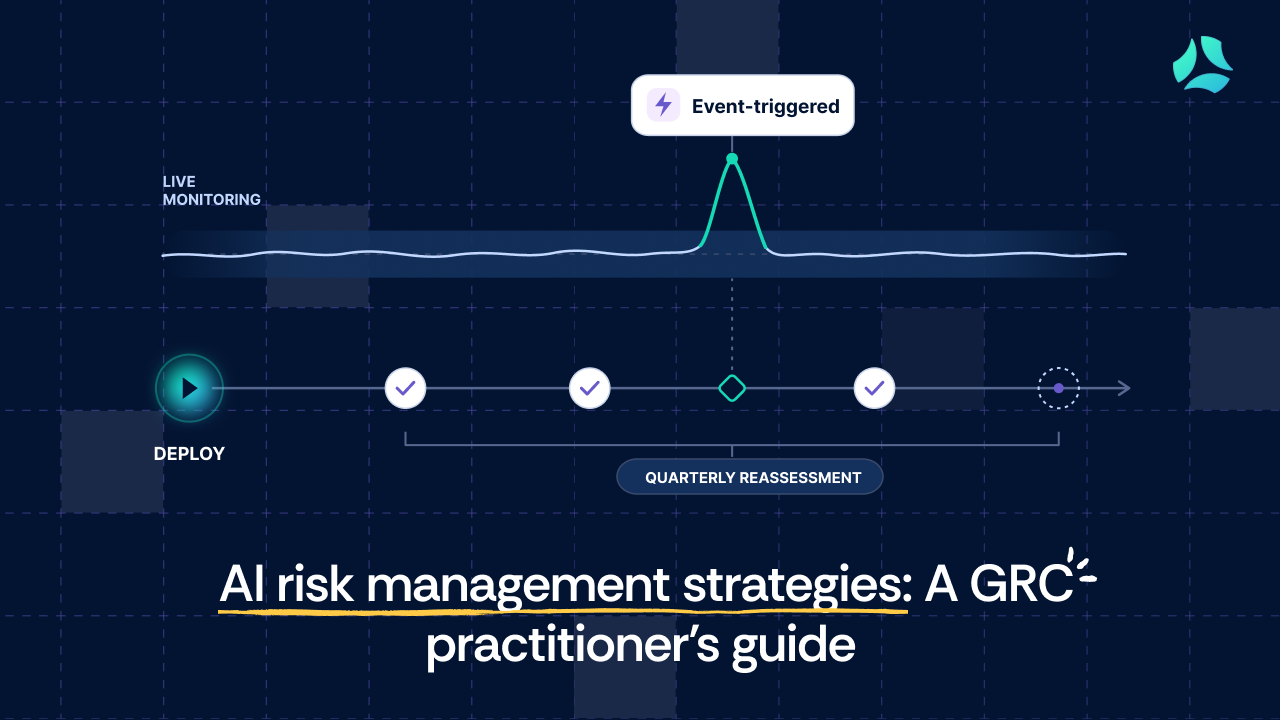
- Quarterly reassessment plus event-triggered reviews are the current practitioner standard for post-deployment AI monitoring.
If you lead compliance, risk, or security at a fast-growing company, you are almost certainly being asked to govern AI systems you did not build, often without a clear regulatory mandate yet in force.
That is the defining tension of AI risk management today: business adoption is moving faster than the frameworks and regulations meant to govern it. (For example: A product team ships an LLM-backed feature this quarter; the guidance on how to secure it is still being drafted.)
This guide is written for the people caught in that gap: Compliance Managers, GRC Leaders, CTOs, and founders who are deploying or evaluating AI systems and need to translate fast-moving expectations into defensible practice.
What follows is a practitioner's view of how to build AI-era risk management that holds up. We cover why AI breaks traditional risk models, the four categories of AI risk you actually have to manage, the frameworks worth adopting, the EU AI Act, and a step-by-step way to start. Along the way, we draw on what generative AI is doing to reshape GRC and on lessons from teams who have already done this work.
Why traditional risk frameworks fall short for AI systems
The current AI moment is easy to summarize: generative AI has moved from novelty to core infrastructure across healthcare, finance, and software in a very short window, and adoption has outrun the controls meant to govern it. That speed mismatch is the point. It is also where traditional risk management starts to fail.
Traditional risk management assumes a deterministic system. You test a control, it passes or fails, and you can reasonably expect it to behave the same way tomorrow. AI systems are stochastic. The same input can produce different outputs, which means a point-in-time control test no longer confirms consistent behavior across future queries. A clean result on the day you test is not evidence that the system is safe next week.
Three characteristics make AI a distinct risk problem.
Non-deterministic output is the first. An LLM is like a database that does not return what you expect. You put something in and get something interesting out, drawn from a range of possibilities rather than a fixed answer. That is by design, and it is exactly why control testability becomes probabilistic rather than binary.
Unintentional training exposure is the second, and significant enough to warrant its own callout below. When your organization sends data to a third-party model, that model may train on it. This is the risk that separates AI third-party risk from ordinary vendor risk.
You have always trusted cloud providers with your data, but a model regurgitating your confidential information to another customer is a genuinely new failure mode. There are reported cases of confidential code and internal meeting notes being submitted to public LLMs and of interview questions resurfacing in ways that implied prior training exposure.
The blurred shared-responsibility model is the third. With a third-party LLM, you inherit the provider's data retention and security posture, but you rarely have clear visibility into how they change their models or what they do with your prompts. This is like the early cloud era: using a big provider does not absolve you of responsibility for how you use it. Your controls, your architecture, and your guardrails still determine whether you or your customers get hurt
There is a second-order effect worth naming. AI deployment surfaces governance problems that were always there but never addressed. Rolling out an AI assistant across a company forces data classification and access management into the spotlight, because the tool inherits permissions and exposes data that managers assumed people never had access to.
AI usage also spans a wide spectrum, from simple analytics to autonomous decision-making, and the governance obligation scales with how much authority you hand the system.
Continuous assessment, not point-in-time, is the only realistic response. The system keeps changing, so your assessment has to keep pace.
Traditional vs. AI risk management
This is where third-party vendor risk management and continuous compliance monitoring become foundational rather than optional. Both traditional third-party questions still apply to AI vendors, but you have to layer the AI-specific concerns on top.
The four categories of AI risk every compliance leader must manage
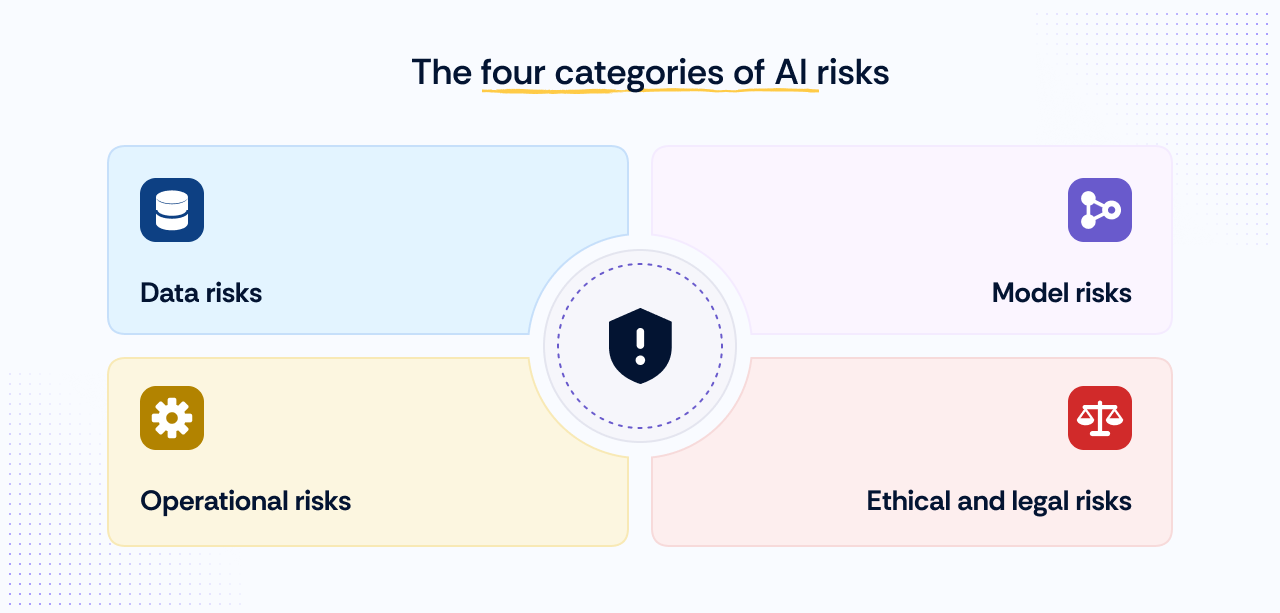
The existing literature lists dozens of AI risks, which is thorough but hard to act on. GRC practitioners and the NIST AI RMF Map function tend to organize them into four buckets. Structuring your risk assessment this way makes it far easier to assign owners and map controls.
1. Data risks
Data risks cover breaches, poisoning, and exposure of sensitive information. The most AI-specific version is unintentional training exposure. Beyond that, attackers can manipulate training data to inject bias or malicious patterns, degrading model integrity from the inside.
Skewed or poisoned training data can produce discriminatory or simply wrong outputs at scale.
For regulated data such as PII and PHI, the core question is whether that data can end up in a model that other parties can query. Getting data classification for AI systems right is the prerequisite for controlling any of this.
The first question to answer for any AI system: what data categories does it touch, and can any of them end up in a model that other parties can query? If the answer is yes or maybe, the data classification and vendor controls need to be in place before the system goes live.
Unintentional training
This is the risk that separates AI vendor risk from ordinary vendor risk. When an employee pastes PII, PHI, trade secrets, or credentials into a third-party LLM, that model may train on the data and later surface it, or something like it, to a different user.
Clawing that data back after the fact is difficult and may be impossible. Reported incidents involving confidential source code and internal meeting notes submitted to public chatbots illustrate how easily this happens.
The mitigations are a clear written policy on what employees may enter into which models, a pre-processing redaction layer that scrubs names, API keys, and PII before prompts leave your environment, and, where sensitivity is high, self-hosting so you retain the ability to understand and roll back what the model has seen. See our deeper treatment of LLMs and third-party risk.
2. Model risks
Model risks target the model itself. Prompt injection is the most important and most under-covered. It is a form of input injection that tricks a system into violating its own security policy. Unlike SQL injection, there is no clean fix because generative models are designed to accept unstructured input. There are two flavors.
Direct prompt injection is when a malicious user manipulates the model directly, for example, by getting it to produce instructions it was configured to refuse. Security researchers routinely bypass safety layers using techniques such as payload splitting, where the same instruction is broken across two prompts and the model is told to combine and execute them.
A worst-case direct injection would be a customer-facing chatbot connected to a backend function that an attacker coerces into shutting down a service or exfiltrating data.
Indirect prompt injection is more insidious because the model operator is acting in good faith but stumbles onto maliciously crafted content. A web page can embed hidden instructions that an autonomous agent ingests and executes.
Mitigations include rules-based input filtering, using a supervisory LLM to inspect prompts for hidden malicious content, tightly restricting which data sources the model can reach, and putting non-LLM logic checks around any function the model can call. None of these is a silver bullet. Prompt injection is a risk to manage continuously, not solve once.
Model risks also include model inversion, where attackers reverse-engineer a model to recover training data, and backdoor attacks, where hidden triggers are planted during training.
3. Operational risks
Operational risks emerge once a system is live. Model drift is the headline: models degrade as the world shifts underneath them, and a fraud-detection or compliance model that was accurate at launch can quietly become unreliable as patterns change. Misconfiguration is another large contributor. Self-hosted models add exactly this surface.
Integration vulnerabilities and an absence of clear accountability round out the category. If no named human owns a control, no one is watching when it fails.
4. Ethical and legal risks
This category covers bias, non-compliance, lack of explainability, copyright exposure, and hallucination in decision-making contexts.
AI trained on historical hiring decisions will reflect historical hiring bias. That is not a bug to be patched. It is a structural property of how the model learned.
Copyright is genuinely unsettled: if a generative tool draws heavily on copyrighted material, ownership and attribution of the output are unclear in most jurisdictions.
And hallucination is not a bug to be eliminated but a built-in property of generative models, which is precisely why it is dangerous when outputs are used for decisions.
See our guide to generative AI security risks for more.
Hallucination risk in compliance contexts
AI output can be highly convincing and completely wrong at the same time. Confidence is not accuracy. The danger for compliance teams is accepting an AI-generated policy, control mapping, or evidence summary at face value without human review.
The cleanest way to think about accountability is to borrow from engineering: if AI generates code, the engineer who approves the pull request still owns it. Compliance is identical.
When a model drafts a compliance response, liability sits with the human owner of that control who reviews it and signs off. AI output is a draft until a named, accountable owner approves it.
Learn more about AI hallucinations in GRC.
Real-world examples of AI-related security incidents
Incidents are most useful to compliance leaders when you read them for the risk management failure they reveal, not just the headline.
AI-generated deepfakes. In January 2024, a finance employee in engineering firm Arup’s Hong Kong office joined a video call with what appeared to be the company’s CFO and several colleagues. Every other participant was a deepfake, and the employee went on to authorize 15 transfers totaling about $25 million. Arup later confirmed that fake voices and images were used.
Risk management lesson: Identity verification controls that assume media is authentic are no longer safe assumptions.
AI-enhanced cyberattacks. In mid-September 2025, Anthropic detected and disrupted a cyber espionage campaign by a group it assessed as Chinese state-sponsored. The attackers manipulated an AI coding agent into carrying out reconnaissance, exploitation, credential harvesting, and data exfiltration largely on its own. Human operators mostly stepped in to authorize key decisions.
Risk management lesson: Detective controls tuned to human-speed attacks will lag machine-speed ones, so monitoring cadence has to increase.
AI-driven phishing. In May 2024, the FBI’s San Francisco division warned that cybercriminals were using AI tools to write targeted phishing messages with correct grammar and spelling. That defeats the old “look for typos” advice.
Risk management lesson: Security awareness training and email controls must be recalibrated for AI-quality lures.
AI-enhanced social engineering. Attackers use AI to analyze large volumes of public data and build convincing pretexts at scale. The Arup case followed this pattern. The employee was initially suspicious of a message requesting a confidential transaction, and the follow-up video call was what overcame that doubt.
Risk management lesson: Process controls, such as out-of-band verification for sensitive actions, matter more than ever because the human is the target.
LLM prompt injection leading to data exfiltration. EchoLeak (CVE-2025-32711) was a vulnerability in Microsoft 365 Copilot, disclosed by Aim Security and patched by Microsoft in June 2025. It showed that a single crafted email could cause the assistant to leak sensitive data without the user clicking anything.
Microsoft reported no evidence of malicious exploitation. The plugin-chaining scenario described earlier, which a practitioner shared in our expert interview, works the same way: a browsing agent ingests malicious instructions from a web page and exfiltrates data from a connected email account.
Risk management lesson: Autonomous agents with access to sensitive systems need strict scoping and human-in-the-loop authorization for consequential actions.
What this means for compliance leaders. Across these examples, AI mostly accelerates and scales existing categories of failure rather than inventing new ones. It also adds a few genuinely new vectors, such as prompt injection. Your controls need to move from periodic to continuous, and your AI incident response planning needs to account for AI-specific scenarios. Treating AI outputs as authoritative when they may be wrong is itself a business risk, so build validation into any workflow where an AI output drives a decision. For more on the incident types AI amplifies, see our guide to AI-enhanced security incidents.
Drawbacks of traditional risk management methods for AI systems
Traditional risk management falls short in the AI context for five connected reasons.
1. Complexity of AI systems. A control library scoped once and left alone will drift out of alignment with the system it is supposed to govern within months. AI systems are highly dynamic and evolve continuously, and static assessment methods cannot keep pace.
2. Data-driven nature. AI's reliance on data introduces risks, from bias in training sets to breaches of the data itself, that traditional risk management was never designed to catch. A standard IT risk assessment rarely asks where training data came from or whether it could resurface. That is exactly the question an ISO 42001 auditor will ask.
3. Non-deterministic behavior. Because outputs vary, risk is harder to predict and mitigate. A point-in-time SOC 2 control test does not confirm that a model will behave consistently across all future queries, so one clean test cannot be treated as ongoing assurance.
4. Continuous adaptation. Models learn and change over time. The practical consequence is that a control library scoped once and left alone will drift out of alignment with the system it governs within months, not years. The quarterly reassessment cadence covered in the next section exists precisely because traditional annual reviews cannot catch that drift in time.
5. Compliance and reputational risks. AI can create compliance and reputational exposure faster than a periodic function can react. Regulatory expectations are evolving quickly, and a controversy or enforcement action can arrive well inside a traditional annual review cycle.
The through-line is that AI risk management demands you define your risk tolerance and appetite up front, calibrated to context, because the framework will not do it for you. A meme generator and an autonomous decision engine sit at opposite ends of the risk spectrum and warrant completely different tolerances.
Deciding where each system sits, before deployment, is the work that traditional methods skip. That is the bridge to a framework-based approach: the frameworks give you structure, but you supply the context and the tolerance. Building an effective risk management process for AI means adapting these compliance frameworks to how your organization actually uses AI.
Why AI risk management must be continuous, not periodic
Picture a fraud-detection model trained on last year's fraud patterns. As fraudsters change tactics, the model's accuracy quietly erodes, false negatives climb, and the failure only becomes visible when losses spike or an auditor asks for effectiveness evidence you cannot produce. In a compliance context, the same drift shows up as a control-monitoring model that stops catching the exceptions it was built to catch.
That is what makes drift a risk management failure. It is silent.
Continuous learning and model drift. Because models keep learning from new data, their performance can degrade in ways that are invisible until something breaks. This is the heart of the shift from point-in-time to continuous risk management.
Plan for post-deployment effort. If your entire budget and attention go into pre-launch assessment, you have under-resourced the phase where drift, new attack vectors, and configuration decay actually occur. Budget accordingly.
Set a reassessment cadence. The practitioner standard is a scheduled quarterly reassessment as the baseline, with out-of-cycle reviews triggered by material change. In practice, that means any major release, an authentication change, or a fundamental change to how a feature works triggers an assessment outside the quarterly rhythm.
Quarterly by default, event-driven whenever something material shifts underneath the feature. Build this cadence into your AI risk assessment program rather than treating each review as a one-off project.
From monitoring to decision-making. The output of continuous AI risk assessment should not sit in a dashboard. It should feed board-level reporting. In practice, that means arriving at a board meeting able to answer three questions: which AI systems are we running, what risk category does each carry, and what changed since last quarter? Boards are no longer satisfied with a green compliance dashboard.
They want to know whether the fraud-detection model is still accurate, whether the customer-facing chatbot has had any prompt injection attempts, and whether the vendor running your LLM infrastructure changed their data retention policy. A CISO or GRC Manager who can answer those questions with evidence, not just assurances, is doing the job the moment requires.
Tying this into your broader continuous AI compliance program is what turns monitoring into governance.
Key components of continuous AI risk management
A structured continuous program rests on four components.
1. Ongoing threat assessment. Continuous monitoring of AI systems starts with a dedicated logging and tracing solution built specifically for AI agents. Standard application logs miss the interesting behavior: the prompts, the tool calls, the model's decisions.
Purpose-built LLM observability tools, Langfuse and LangSmith are two examples referenced here as a category rather than an endorsement, surface how accurately agents call tools, whether they pick the right tool, and full auditing of LLM calls including token usage, cost per call, and latency.
The artifact set a compliance leader should maintain: agent activity logs, tool-call accuracy metrics, and a PII redaction layer on those traces. That redaction layer is not optional. The moment you log the full prompt and response, you may be logging usernames, PII, and even access tokens and API keys passed into context, which turns your observability tool into your single biggest data-leak surface. Minimum viable monitoring is tracing plus PII scrubbing, not tracing alone.
2. Adaptive compliance frameworks. Your compliance approach has to flex as AI standards and regulations evolve, and compliance checks belong across the whole AI lifecycle, from design through deployment.
ISO 42001 and the NIST AI RMF are complementary instruments, not redundant ones. NIST publications like the AI RMF are frameworks in the business-school sense: comprehensive but non-prescriptive, meant to help you structure your own decision-making.
ISO 42001 is different in that it expects you to have something fulfilling each role of an AI management system, implemented in your context. Use the NIST AI RMF for voluntary operational guidance and ISO 42001 when certification is a customer or market requirement. Our comparison of NIST AI RMF vs ISO 42001 walks through this in detail.
3. Collaboration and information sharing. Effective AI risk management requires legal, compliance, data, and engineering at the same table, and not just for the initial rollout. Rolling out an AI tool forces conversations about data classification and access governance that no single function can resolve alone.
Security cannot enforce data classification by fiat; it requires business owners to know what data their systems touch, data protection teams to apply the right controls, and engineering to implement them.
In practice, this means standing up a cross-functional AI review process, even an informal one, where a new AI tool cannot go to production without sign-off from legal (copyright and privacy), compliance (framework implications), and engineering (security architecture). That process is what makes the inventory, monitoring, and framework components actually work. See how this plays out in collaborative AI governance.
4. AI tool inventory and lifecycle governance. This is the component most programs miss, and it is explicitly expected under ISO 42001. Auditors expect an inventory of the AI tools your organization uses to build its own AI systems, directly analogous to a vendor inventory.
Every entry in that inventory should answer three questions: what AI system is this? What role does the organization play with respect to it (provider, producer, or user)? And what data does it process? The role determination matters because it dictates which controls apply. Maintaining this inventory is the baseline for any structured AI risk program and a prerequisite for AI risk assessments under ISO 42001.
Increasingly, running this at scale is a job for GRC automation for AI compliance rather than a spreadsheet, because tools, models, and data flows change too fast to track manually. For the standard itself, see our overview of the ISO 42001 AI management system.
AI risk management framework (NIST)
The NIST AI Risk Management Framework is the most widely referenced voluntary framework for governing AI. It is organized around four core functions.
Govern establishes the culture, policies, roles, and accountability structures for managing AI risk across the organization. It is the connective tissue that makes the other three functions operate consistently rather than as one-off exercises.
Map builds the context. It identifies where and how AI is used, who the stakeholders are, and what could go wrong given that context. This is where the four risk categories, data, model, operational, and ethical/legal, get enumerated for your specific systems.
Measure assesses and tracks the identified risks using quantitative and qualitative methods, including testing for trustworthiness characteristics like validity, reliability, and fairness. This is where you determine whether a control is actually working.
Manage is where the risk register becomes a budget conversation. Resources get allocated to the risks that matter, and the treatment decisions, accept, mitigate, transfer, or avoid, feed back into Govern. This is the loop that makes the framework continuous rather than a one-time exercise.
A candid practitioner critique is essential here. Like many NIST frameworks, the AI RMF is high-level and comprehensive but not prescriptive. It talks extensively about risk appetite and risk tolerance but does not give you a road map for determining what those should be for your organization. That translation work is significant, and it falls on you.
Risk appetite and risk tolerance are not the same thing, and conflating them is the most common mistake teams make when reading the AI RMF. Appetite is the strategic declaration: how much risk leadership is willing to accept in pursuit of the objective. Tolerance is the operational threshold: the specific point at which residual risk requires escalation. Define both, in writing, before the system goes live.
The intuitive way to see this: an AI meme generator can carry a high risk appetite because a wrong or even offensive output has low impact, whereas an autonomous vehicle carries a very low (but never zero) appetite. Context drives tolerance, and tolerance drives which controls you build. You will never move risk to zero, and trying to will trap you in an unwinnable loop.
Two additional NIST resources are worth knowing. In July 2024, NIST released the Generative AI Profile (NIST-AI-600-1), a companion resource for organizations specifically managing generative AI risks. Separately, NIST has signaled work on an AI RMF Profile for Trustworthy AI in Critical Infrastructure (a concept note associated with April 2026).
Comparison of NIST AI RMF vs. ISO/IEC 42001
For deeper reading, see the NIST AI Risk Management Framework overview, our practical guide to applying the NIST AI RMF, and the ISO 42001 implementation guide. If you are pursuing the framework formally, NIST AI RMF compliance with Scrut shows how the four functions map to controls.
The EU AI Act and emerging regulatory requirements
If your AI systems touch the EU market, the EU AI Act applies to you, regardless of where your organization is based. The European Union has the most comprehensive enacted AI law to date, and the Act’s obligations are already in motion.
The Act uses a risk-based classification with four tiers. Prohibited systems present unacceptable risk and are banned outright. High-risk systems face the heaviest obligations around risk management, data governance, documentation, and human oversight. Limited-risk systems carry transparency obligations, such as disclosing that a user is interacting with AI. Minimal-risk systems face few or no specific obligations. The classification, not the technology, drives the compliance burden.
For compliance leaders, the high-risk category is where attention concentrates. AI used in areas such as creditworthiness and financial-services decisioning, healthcare, and HR functions like hiring and candidate evaluation can fall into high-risk, triggering substantial documentation, testing, and human-oversight requirements. If you operate in these sectors, assume high-risk classification is in play until you have confirmed otherwise.
The Act entered into force on August 1, 2024, and its obligations apply in phases:
- February 2, 2025: Prohibitions on unacceptable-risk practices and AI literacy obligations for providers and deployers.
- August 2, 2025: Obligations for general-purpose AI models.
- August 2, 2026: Most transparency obligations for limited-risk systems.
- December 2, 2027: Obligations for stand-alone high-risk systems, including those used in hiring, creditworthiness assessment, and education.
- August 2, 2028: Obligations for high-risk AI embedded in products already covered by EU product safety law, such as medical devices and machinery.
The last two dates reflect the Digital Omnibus on AI (Regulation (EU) 2026/1744), which entered into force on July 27, 2026 and pushed back the original August 2026 high-risk deadline. The delay changes the timing, not the requirements. Teams that use the extra time to classify their systems and build documentation will be in a far better position than those who wait.
Our overview of EU AI Act compliance requirements tracks the current position, and for smaller teams see EU AI Act compliance for SMBs.
The Act also sets bright-line prohibitions worth flagging to leadership immediately. These include social scoring that leads to unjustified or disproportionate treatment of people, and real-time remote biometric identification in publicly accessible spaces for law enforcement purposes, outside narrow exceptions.
The Digital Omnibus added AI systems that generate non-consensual intimate imagery or child sexual abuse material to the list. These are not risk-managed gray areas. They are hard stops.
Two more points. First, the EU AI Act and GDPR are complementary, not redundant. The AI Act governs how AI systems are built and deployed, while GDPR governs the personal data those systems process, and you have to satisfy both. Minimizing the personal data you collect and process reduces exposure under each. See GDPR compliance and the EU AI Act.
Second, and most important strategically: much of the enforcement landscape will be defined by regulators acting through enforcement rather than by clear ex-ante rules. Early risk identification is worth far more than late remediation. Prediction is cheaper than cure, and identifying your exposure now can save you significant penalty and remediation cost later.
AI system impact assessment: What ISO 42001 auditors actually expect
This section draws directly from Scrut's own ISO 42001 implementation journey, and specifically from the single biggest point of unexpected friction in that process: the AI System Impact Assessment.
The most common and costly mistake is treating the AI System Impact Assessment as a security risk assessment. It is not. Teams initially assume it is the same exercise they run for any IT system, just relabeled for AI. During Scrut's internal audit, this assumption was explicitly flagged as incorrect. A standard security risk assessment looks at confidentiality, integrity, and availability. The AI System Impact Assessment is a distinct document that assesses impact across three dimensions:
- Organizational impact: how deploying the AI system affects your own organization.
- Individual impact: how it affects the people who use or are subject to the system.
- Societal impact: the broader consequences, and this is the dimension most teams miss entirely.
To make the societal dimension concrete: if an AI system generates hiring recommendations or selects individuals, it could produce outcomes biased toward or against a particular community, depending on the selection criteria and environment it operates in. Documenting that potential bias, its affected groups, and its mitigations is a societal impact assessment entry. A security-only lens never surfaces it.
Based on Scrut's implementation, auditors asked for three categories of evidence. First, the AI System Impact Assessment described above. Second, an AI tool inventory, the running list of all AI systems used to build your own AI features, maintained much like a vendor inventory. Third, AI system documentation covering infrastructure, compute resources, the rationale behind key design decisions, how customer data is isolated (and confirmation that customer data is not used to train models), human-in-the-loop review, and ethical and responsible-use considerations.
Notably, this documentation was not just paperwork; it described what the team was actually doing.
Two strategic choices made the implementation manageable. The first is scope limitation. Scrut did not put its entire product in scope. It scoped only the AI security questionnaire feature, which confined implementation and audit readiness to that system and dramatically reduced the burden.
Limiting scope is a legitimate and recommended strategy for a first certification. The second is role determination. ISO 42001 requires you to determine which role your organization plays, provider, producer, or user of AI, because that role dictates which controls apply and shapes your statement of applicability for the AI governance controls. Decide this early.
One practical note on training data: if you do not train models on customer data, the data-provenance controls may be scoped out, but you must be able to demonstrate that clearly, including how any synthetic or external data is handled.
For the full picture, see our ISO 42001 AI system impact assessment guide, the story of how Scrut achieved ISO 42001 certification, and our guide to building an AI management system. The ISO 42001 implementation guide covers the standard end to end.
Building a practical AI risk management strategy: Where to start
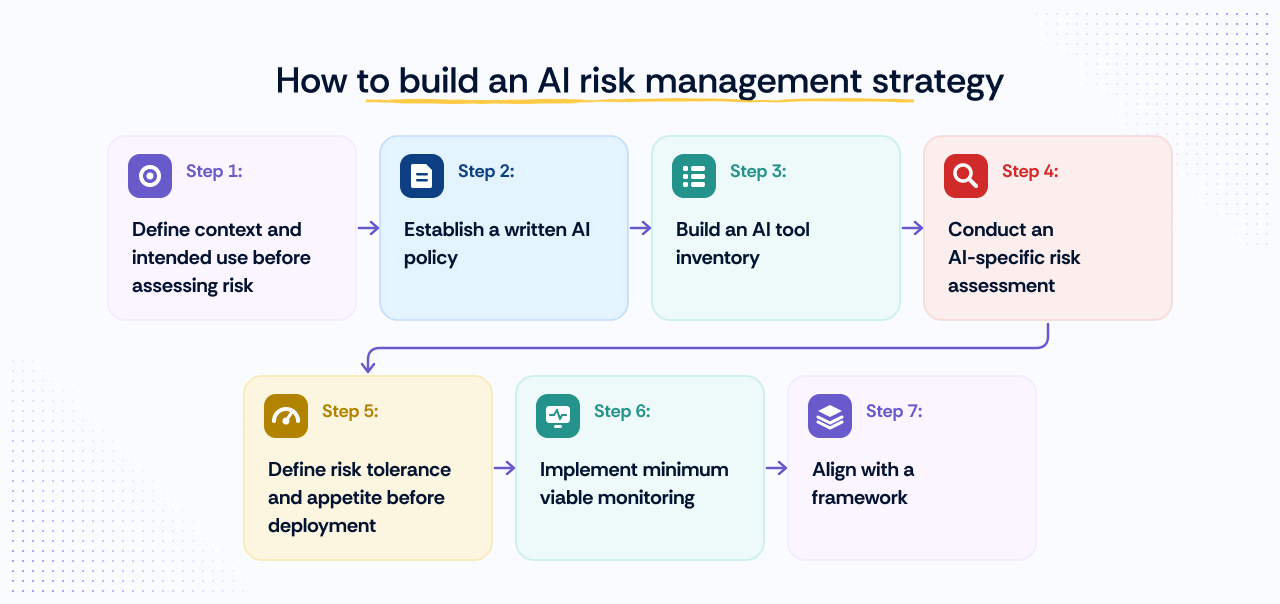
Rather than a category list, treat this as a prioritized sequence. Each step sets up the next.
Step 1: Define context and intended use before assessing risk. Context comes first, always. Before you enumerate risks, document what the AI system is for, its intended purpose, the settings it will be deployed in, and the benefits you expect from it. Context determines risk tolerance, which determines which controls matter. Skipping this step produces a generic risk taxonomy that does not fit your actual system.
Step 2: Establish a written AI policy. Every organization needs a written AI usage policy before tools proliferate into shadow IT. A policy of simply "don't use it" produces shadow adoption and lost visibility, which is worse. The policy should cover acceptable use, what data may and may not be entered into which models, the process for requesting and approving a new tool, and the privacy, security, and legal or copyright review that approval requires. Policy first, technical guardrails second.
Step 3: Build an AI tool inventory. For every AI tool in use, record the organization's role (provider, producer, or user) and a data-sensitivity classification for what it processes. This inventory is both an ISO 42001 requirement and the practical foundation for everything downstream. You cannot assess or monitor what you have not inventoried.
Step 4: Conduct an AI-specific risk assessment. This is not a general IT risk assessment. Work through the four categories, data, model, operational, and ethical/legal, for each inventoried system. The hardest part is usually getting enough context from the engineers and AI practitioners who actually understand how the system works, so budget time for that discovery. Capture the results in an AI risk register.
Step 5: Define risk tolerance and appetite before deployment. Calibrate to context. A low-stakes internal tool and a customer-facing decision engine warrant completely different tolerances. Decide, in writing, what level of residual risk you will accept for each system, and who has the authority to accept it. Our guide to defining AI risk tolerance and risk appetite covers the distinction in depth.
Step 6: Implement minimum viable monitoring. Start with LLM tracing plus a PII redaction layer, tool-call accuracy, and cost-per-call, on a quarterly reassessment cadence with event-triggered reviews. You do not need a full ML-ops drift-monitoring stack on day one for two or three AI features. The heavyweight telemetry earns its place once you have scale or a feature where a wrong answer is genuinely expensive.
Step 7: Align with a framework. Use the NIST AI RMF for operational guidance. Pursue ISO 42001 certification when a customer explicitly asks for it, or when you make a major change to your product, such as adopting AI in a significant new feature. Certification is worth the investment when your customers expect third-party-certified assurances; short of that, framework alignment may be sufficient.
Build the whole program into a coherent AI risk management strategy rather than a set of disconnected controls, and consider running it on a platform, such as AI risk management on the Scrut platform, so the inventory, assessments, and monitoring stay connected. Grounding the whole effort in a responsible AI framework keeps the ethical dimension from becoming an afterthought.
Final thoughts
AI risk management is not a one-time project. The frameworks will not define your risk tolerance, catch your model drift, or answer your auditor's questions. That work is yours, and it is worth starting now rather than after an incident or an enforcement action.
If you do only one thing this quarter, start with an AI tool inventory and a written AI usage policy before tackling framework alignment. Those two artifacts surface most of the shadow AI and data-exposure risk that would otherwise stay invisible, and they are the foundation everything else builds on.
Early risk identification is dramatically cheaper than late remediation. The organizations that treat AI risk as an ongoing capability will be far better positioned when regulatory enforcement accelerates. If you want a system of record that keeps your AI inventory, risk assessments, and continuous monitoring connected, explore Scrut's AI risk management capabilities, and see how it fits into a broader AI compliance program.
Start with context and a written AI usage policy, build an AI tool inventory, run an AI-specific risk assessment across the four risk categories (data, model, operational, ethical/legal), define risk tolerance before deployment, implement minimum viable monitoring (LLM tracing plus PII redaction), and align with a framework. Treat the whole thing as continuous, not a one-time exercise.
The NIST AI RMF is a voluntary, high-level guidance framework organized around four functions (Govern, Map, Measure, Manage) that helps you structure your own decisions. ISO 42001 is a certifiable management system standard that produces a third-party certificate and expects control-specific, auditable evidence. They are complementary, not conflicting. Use NIST for operational guidance and ISO 42001 when certification is a customer or market requirement.
The practitioner baseline is a scheduled quarterly reassessment, plus out-of-cycle reviews triggered by material change such as a major release, an authentication change, or a fundamental change to how a feature works.
Prompt injection is an attack that tricks an AI system into violating its own security policy through crafted input. Direct prompt injection comes from a malicious user; indirect prompt injection comes from malicious content the model encounters, such as hidden instructions on a web page. It is hard to fully prevent because generative models are designed to accept unstructured input, so there is no finite list of "safe" inputs. It is a risk to manage continuously with layered controls, not solve once.
The human owner of the control who reviews and approves it. The cleanest parallel is engineering: if AI writes code, the engineer who approves the pull request still owns it. AI-generated compliance output is a draft until a named, accountable human signs off.